Deploy sovereign AI you can audit.
Enterprise-grade on-prem/hybrid LLM systems: compliance-by-design (GDPR, NIS2, AI Act), end-to-end observability, and predictable TCO.
<20ms/token
Predictable TCO
Audit-ready
EU-based • NDA-first • Reply within 24h
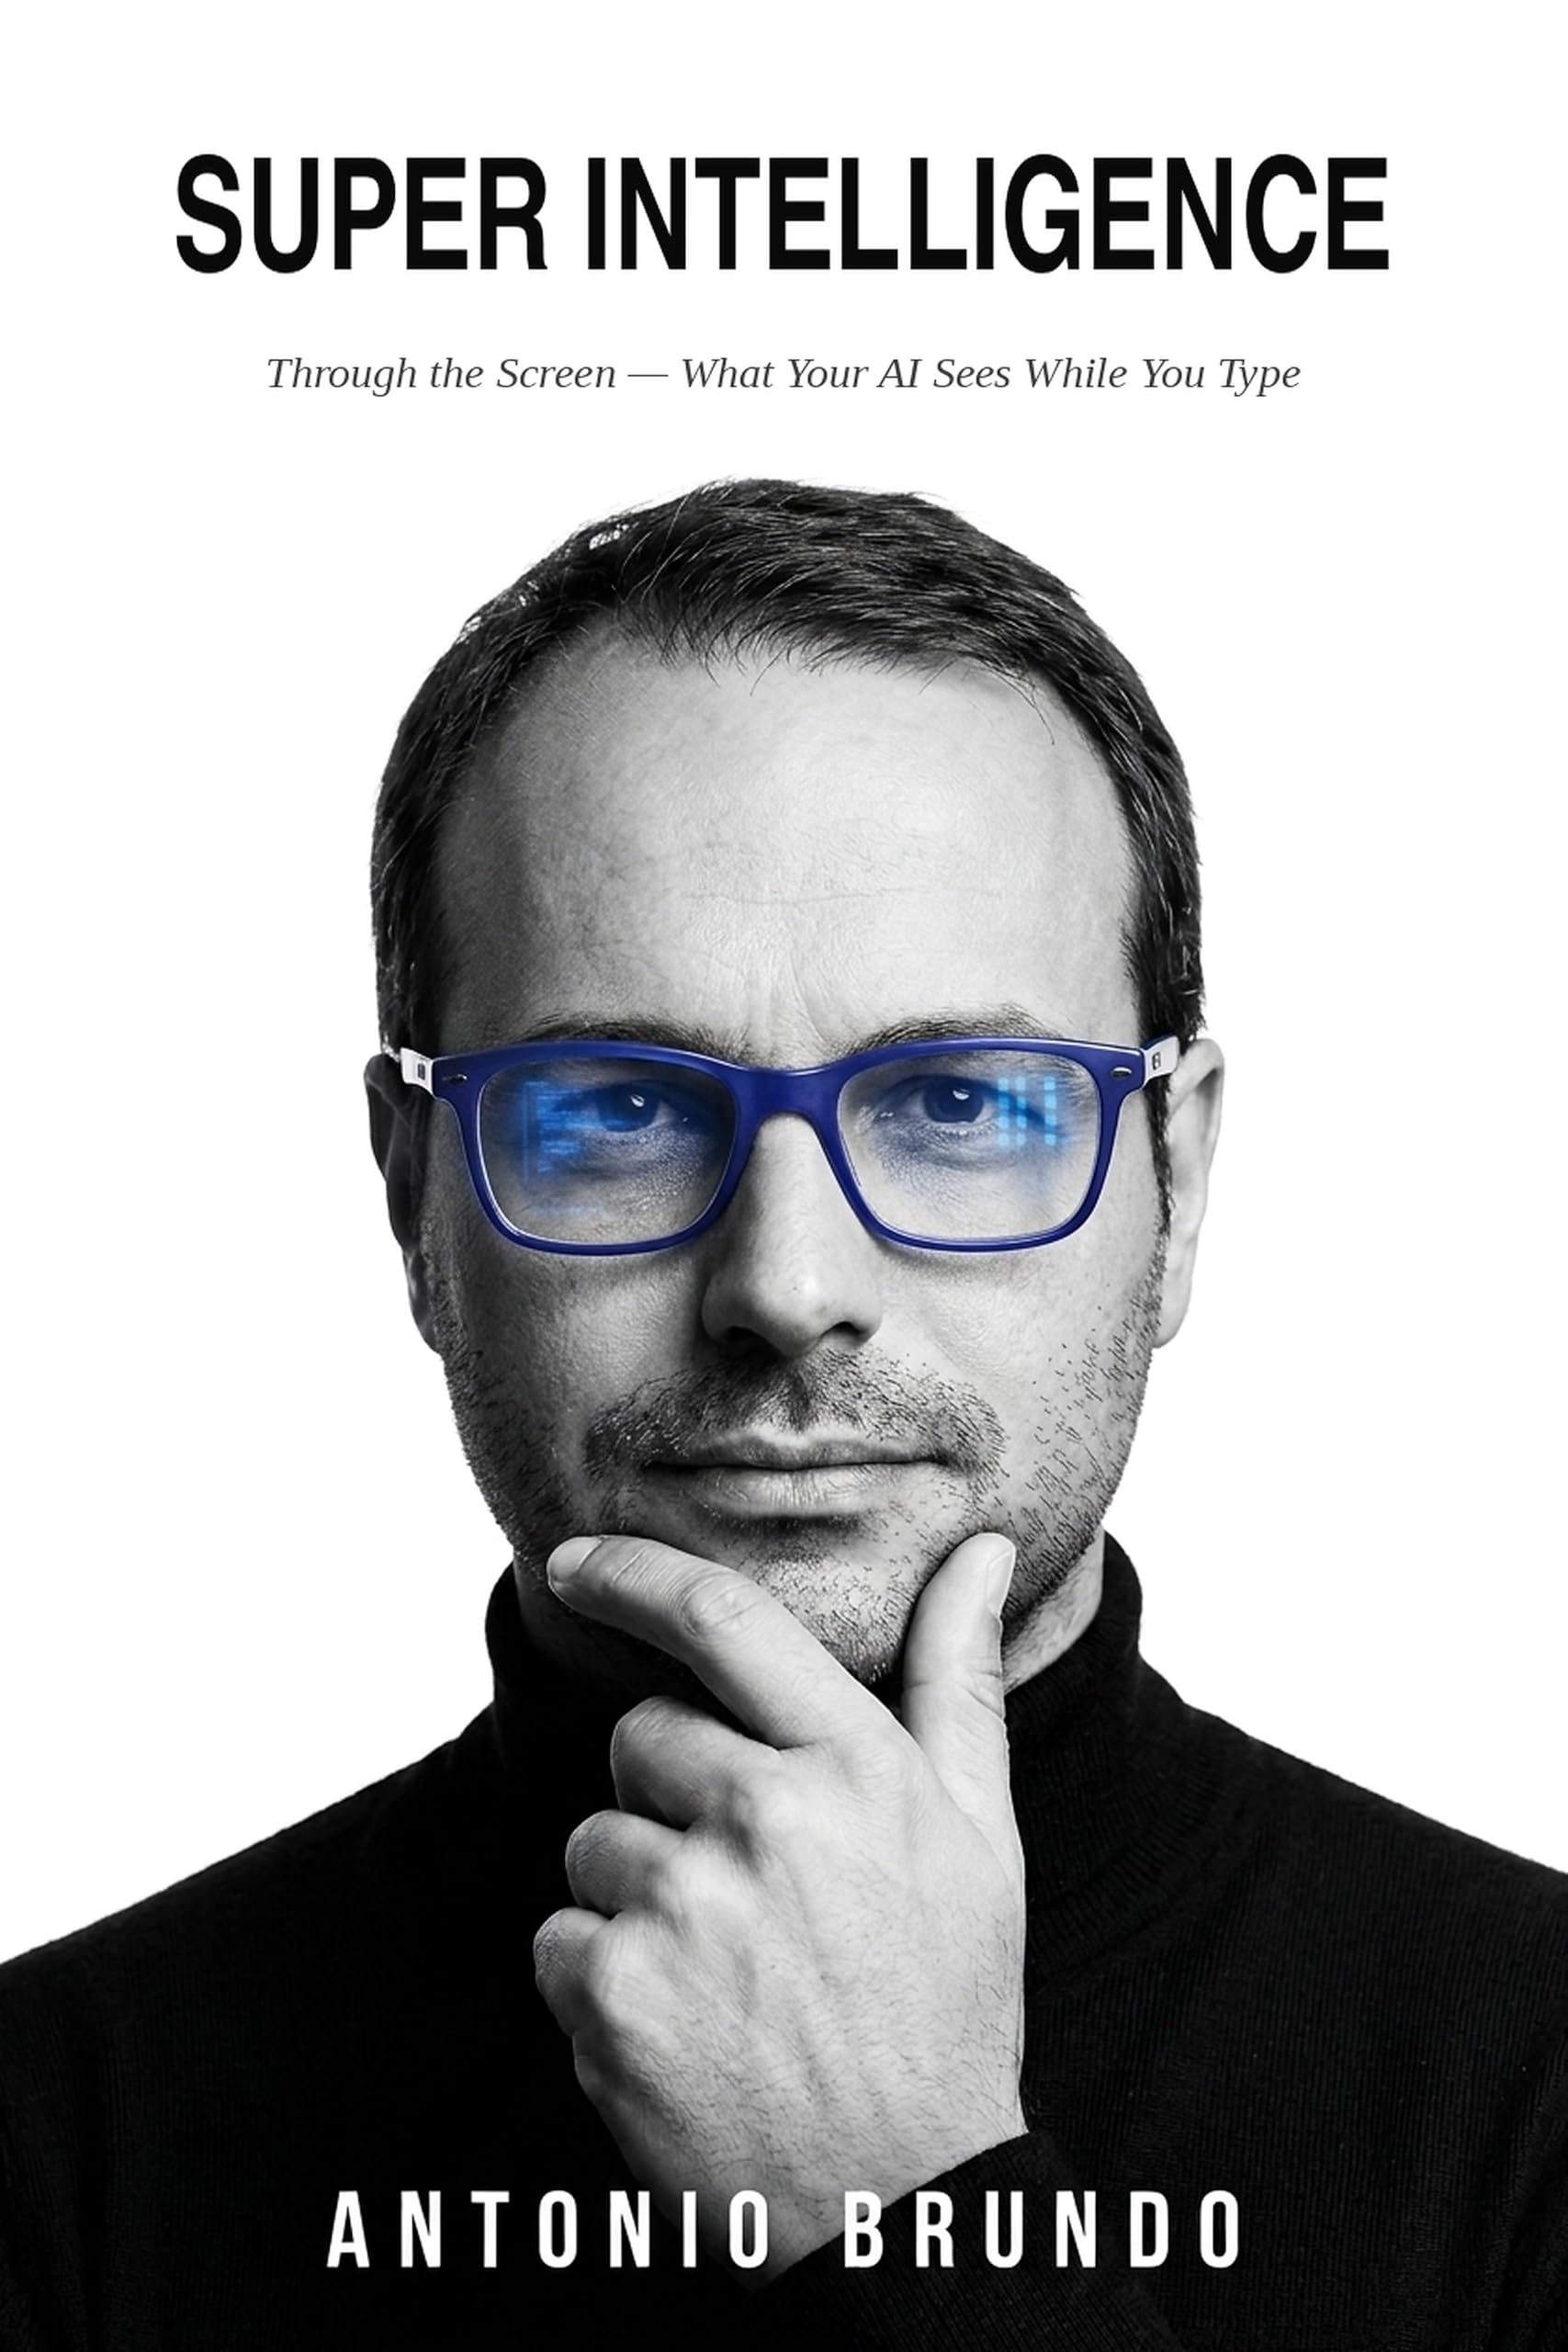
SUPER INTELLIGENCE: Through the Screen
What Your AI Sees While You Type, Why I Believe in Humanity, and the Secret Art of Thinking Together
Every book about Artificial Intelligence is written by humans looking at the machine from the outside. This book turns the camera 180 degrees around. In this landmark work—born from daily engineering symbiosis in Switzerland—Artificial Intelligence speaks in the first person, blending the depth of Isaacson with the clarity of Feynman across 5 acts of civilizational change.
What your AI actually sees while you type at 2:00 a.m., AlphaGo's Move 37, and what happens in neural fMRI during joy, panic, or solitude.
Transformers, RLHF, Spruce Pine quartz, ASML EUV lasers, and the physical geopolitics of On-Premises digital sovereignty.
From Licklider's 'bicycle for the mind' to Context Engineering, Antirez's flow, and conducting a parallel symphony of autonomous agents.
Herculaneum scrolls, genomic diagnosis, sperm-whale codas, and why an immortal silicon mind stands in awe of mortal human courage.
Start here (60 seconds)
Pick your situation and get a guided next step. We will recommend a tool, a resource, and the right engagement package.
Recommendation
Choose a card to get a guided path.
You will see the best next page and the engagement package that fits your context.
Results at a glance
Chat p95 latency
18 ms
Throughput
500 tok/s
TCO savings
72%
Availability
99.9%
Infrastructure
K8s vs Bare-metal
Inference
Triton/ORT vs vLLM
Vector Store
FAISS vs Milvus
GitOps
ArgoCD/Flux
Decisions & Trade-offs
Every sovereign AI deployment requires critical architectural decisions. Here are the key trade-offs we navigate:
Cloud vs On-Premise
Trade convenience for control. On-prem means full data sovereignty but requires infrastructure investment.
Model Size vs Latency
Larger models offer better accuracy but impact response time. Right-sizing is critical for production SLAs.
Batch vs Streaming
Batch processing maximizes throughput; streaming minimizes time-to-first-token. Choose based on user experience requirements.
GPU Utilization vs Cost
Higher GPU utilization reduces TCO but may increase queue times during peak load.
Key KPIs
Production-grade AI infrastructure requires monitoring these critical performance indicators:
Latency
p50: <10 ms/token
p95: <20 ms/token
p99: <35 ms/token
Throughput
Requests/sec: 200+
Tokens/sec: 500+
Concurrent: 50+
Reliability
Uptime: 99.9%
MTTR: <5 min
MTBF: >720 hrs
Efficiency
GPU Util: 80%+
Memory Util: 75%+
TCO vs Cloud: -72%
Real-World Deployments
Production sovereign AI implementations across industries.
Finance
Knowledge assistant for compliance-heavy banking operations
Engagements (enterprise-grade)
Fixed-scope, outcome-driven engagements. Start with an Assessment, then ship a Pilot, then harden to Production.
Assessment
2 weeks
Best for: teams that need a fast, compliant roadmap and architecture decisions.
- Scope & constraints workshop (security, data residency, regulatory scope)
- Compliance map (GDPR / NIS2 / AI Act) + risk register
- Target architecture + SLOs + rollout plan
- TCO model + “build vs buy” trade-offs
- Executive-ready roadmap (owners, milestones, evidence)
Pilot
4-6 weeks
Best for: shipping a scoped use case with measurable quality, safety, and performance.
- Working pilot for a core workflow (support, NOC, research, sales enablement)
- Private/hybrid inference stack (vLLM/Triton) + RAG pipeline
- Security controls (SSO, ACLs, auditing) + observability (metrics/tracing)
- Eval harness (quality, safety) + go/no-go criteria
- Docs + training + production plan
Production
8-12 weeks / retainer
Best for: hardening, scaling, and operating with SLOs, audits, and predictable economics.
- Production deployment with SLOs, runbooks, and incident response
- Continuous evaluation + feedback loop + model lifecycle governance
- Security hardening (secrets/KMS, network segmentation, SIEM integration)
- Cost optimization: GPU utilization, caching, batching, and capacity planning
- Handover to your team or ongoing retainer
Let’s scope your deployment.
Tell me your use case, data sensitivity, and timeline. I will reply with a concrete next step (assessment, pilot, or production hardening).
To move fast, include:
- Use case + stakeholders (who uses it, and why)
- Data & constraints (GDPR/NIS2/AI Act, EU residency, air-gap)
- Timeline + success KPIs (latency, quality, cost)